How to Standardize Interview Scorecards Across Hiring Managers
Rakesh · October 11, 2026 · 15 min read
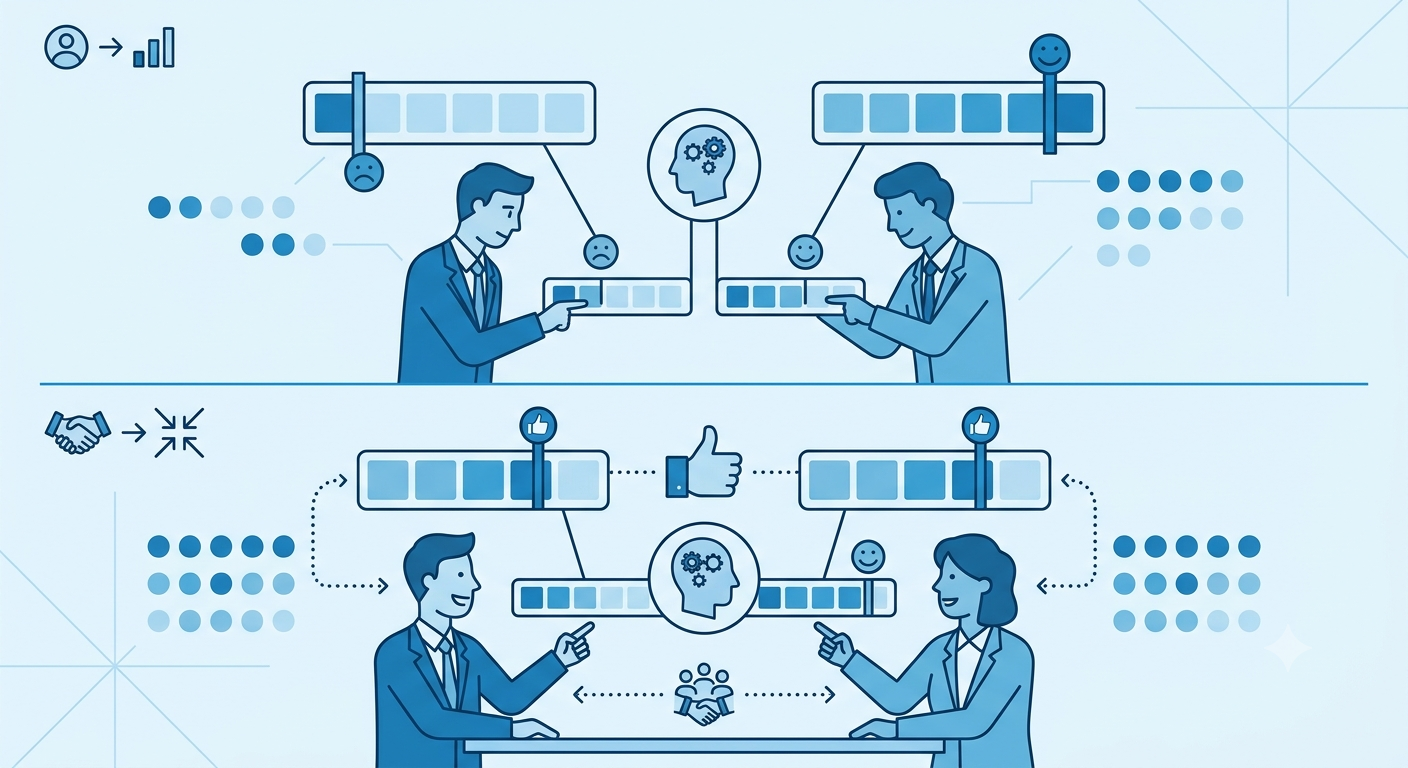
Two hiring managers interview the same candidate, on the same panel, for the same role — and walk away with genuinely different ratings. One calls the candidate a clear "strong yes." The other rates them "borderline." Neither is necessarily wrong; they're likely just applying different internal standards to the same evidence, because nothing forced their definitions of "strong" and "borderline" to actually mean the same thing. This is the core problem interview scorecard standardization is meant to solve — and it's a genuinely common failure mode even at organizations that already use scorecards.
Why Scorecards Alone Don't Guarantee Consistency
A scorecard's existence isn't the same thing as its standardization. A scorecard only functions as a real calibration tool when every interviewer evaluating candidates for the same role is using the same competencies, the same rating scale, and — critically — the same shared understanding of what each rating level actually looks like in practice. Without that shared understanding, a "3 out of 5" from one interviewer and a "3 out of 5" from another can represent genuinely different standards, even though the numbers look identical on paper.
The well-established academic case for structure itself remains strong. Schmidt and Hunter's landmark 1998 meta-analysis, published in Psychological Bulletin and synthesizing 85 years of personnel-selection research, found that structured interviews substantially outperform unstructured ones in predicting job performance — a finding reinforced by a 2022 re-analysis (Sackett, Zhang, Berry, and Lievens, published in the Journal of Applied Psychology) that identified structured interviews as the single strongest predictor of job performance among all selection methods studied. This is genuine, peer-reviewed, well-replicated research, and it's the strongest evidence available that structure itself matters.
A note on the numbers you'll encounter elsewhere on this topic: search around interview scorecard standardization and you'll quickly run into very specific, confidently stated claims — exact percentages for how much "inter-rater reliability" improves with calibration, precise before-and-after case studies with named improvement figures. In researching this piece, several of these numbers turned out to be mutually inconsistent across sources, or attached to case studies with no verifiable underlying organization — a pattern worth being skeptical of. This article focuses instead on the well-established academic backing above and on practitioner-consensus practices that show up consistently across genuine hiring-operations guidance, rather than repeating specific statistics that couldn't be independently confirmed.
The reframe worth internalizing: Standardization isn't primarily about the scorecard document itself — a template is easy to create and easy to ignore. It's about the calibration process that ensures every interviewer's internal definition of each rating level is actually aligned with everyone else's, which requires deliberate, recurring practice, not a one-time rollout.
Why Hiring Managers Score the Same Candidate Differently
1. Rating Scales Without Behavioral Anchors Are Inherently Subjective
A numeric scale (1 to 5, for instance) without a specific description of what each number actually represents leaves every interviewer to define "good" for themselves. One manager's internal bar for a "4" may be another's "5" — not because either is wrong, but because nothing forced their definitions to converge in the first place.
2. Too Many Competencies Dilute Evaluation Quality
A scorecard trying to assess a large number of competencies in a single interview round tends to produce rushed, less reliable ratings — interviewers under time pressure default to a midpoint rating across the board rather than genuinely differentiating, which defeats the purpose of scoring at all. A commonly recommended practical cap is somewhere in the range of four to six competencies per interview round, focused specifically on what actually predicts success in the role rather than every conceivably relevant trait.
3. No Shared Reference Point for What "Evidence" Looks Like
Without a requirement to justify each rating with a specific example from the actual conversation, ratings become closer to gut impressions dressed up as data — two interviewers can walk away with the same overall impression ("I liked them") but attach very different numbers to it, since neither rating was ever forced to be traceable back to something concrete and comparable.
4. No Calibration Practice Before Real Interviews Begin
Interviewers who've never compared notes against each other on a shared example — a recorded interview, a written sample response — have no actual reference point for whether their internal standards match anyone else's. The first real candidate becomes the first calibration attempt, which is both too late and too consequential a moment to discover a significant scoring mismatch.
5. Equal Weighting Across Genuinely Unequal Competencies
If every competency on a scorecard is weighted identically regardless of its actual importance to the role, a strong score on a less critical dimension can offset a weak score on the dimension that actually matters most — producing an overall rating that looks reasonable on paper but doesn't reflect the panel's real judgment about the candidate's fit for what the role actually requires.
A Practical Framework: Building and Calibrating a Standardized Scorecard
Step 1 — Define a Focused Set of Role-Relevant Competencies
Identify the specific competencies (commonly capped around four to six per round) that genuinely predict success in the role, rather than an exhaustive list of every conceivably relevant trait. Map each competency clearly to a specific interview round, so interviewers know precisely what they're responsible for assessing.
Step 2 — Write Behavioral Anchors for Every Rating Level
For each competency, describe concretely what a "1," a "3," and a "5" (or whatever scale is in use) actually looks like in practice — specific, observable behavior, not vague adjectives. This is the single highest-leverage step in making ratings genuinely comparable across different interviewers.
Step 3 — Require an Evidence Line for Every Rating
Every score should be accompanied by a specific, concrete example from the actual interview that justifies it — not just a number. This keeps ratings traceable and gives later reviewers (or a future calibration session) something real to evaluate and discuss, rather than an unexplained score.
Step 4 — Run Calibration Sessions Using Shared Examples
Before interviewers evaluate live candidates, have the full panel independently score the same shared example — a recorded interview or a written sample response — and then compare results directly. Where ratings diverge meaningfully, the conversation should focus specifically on refining the behavioral anchors until they're precise enough to produce consistent ratings, not simply on convincing one interviewer to adopt the other's opinion for this one instance.
Step 5 — Weight Competencies by Actual Importance to the Role
Rather than treating every competency as equally important by default, apply deliberate weighting that reflects which dimensions genuinely matter most for a given role — ensuring the overall score reflects the panel's real judgment rather than an arithmetic artifact of equal weighting.
Step 6 — Recalibrate on a Recurring Basis, Not Just at Rollout
Scoring standards can drift over time, particularly as new interviewers join a panel or as role requirements evolve. Treat calibration as an ongoing practice — commonly recommended on a quarterly basis, or whenever new interviewers join a panel — rather than a one-time training completed at initial rollout and never revisited.
Step 7 — Periodically Check Whether Ratings Actually Predict Performance
Where feasible, compare scorecard ratings against actual on-the-job performance for people who were hired, several months after they start. If ratings show no meaningful relationship to real performance outcomes, that's a signal the competencies themselves — not just the calibration process — need to be reconsidered.
A Practical Checklist: Standardizing Scorecards Across Your Hiring Managers
Cap each interview round at roughly four to six focused, role-relevant competencies
Write specific behavioral anchors describing what each rating level actually looks like
Require a concrete evidence line for every rating, not just a number
Run a calibration session using a shared example before interviewers evaluate live candidates
Apply deliberate competency weighting rather than defaulting to equal weighting across all dimensions
Recalibrate on a recurring basis (commonly quarterly, or when new interviewers join), not just once at rollout
Periodically compare scorecard ratings against actual post-hire performance where feasible
Global Perspective: Scorecard Standardization Considerations by Region
🇦🇺 Australia
With vacancy fill rates declining to roughly 68.2% nationally (Jobs and Skills Australia, March 2026) and persistent skills mismatches in technical roles, standardized scoring is particularly valuable in the Australian market for distinguishing genuinely capable candidates from those who simply interview well, in a talent pool where every miscalibrated hiring decision is costlier to recover from.
🇺🇸 United States
The strongest available academic backing for structured interviewing (Schmidt & Hunter, Sackett et al.) originates largely from U.S.-based industrial-organizational psychology research, and U.S. hiring operations content provides the most detailed practical guidance on calibration mechanics specifically.
🇬🇧 United Kingdom
CIPD data showing 41% of UK new hires resigning within their first 12 weeks suggests that scoring consistency matters beyond just the hiring decision itself — a miscalibrated evaluation that overlooks a genuine mismatch between candidate and role may contribute to exactly this kind of early attrition.
🇪🇺 Europe (broad view)
In markets with stronger employee protections and more formalized hiring documentation requirements, a standardized, evidence-based scorecard also serves a practical defensibility function beyond just decision quality, since documented, consistent criteria are easier to justify if a hiring decision is ever challenged.
🇮🇳 India
With 82% of Indian employers reporting difficulty filling roles (ManpowerGroup's 2026 Talent Shortage Survey), particularly for scarce AI-related technical skills, standardized, well-calibrated scoring is especially valuable for accurately identifying genuine capability in a market where competition for a thin pool of qualified technical candidates is intense.
What Most Articles Get Wrong
Most content on this topic treats a scorecard template as the whole solution — as if simply distributing a shared form to every interviewer automatically produces consistent scoring. It doesn't. A scorecard is only a calibration tool if the people using it have gone through a deliberate process of aligning their standards against each other — otherwise, as this piece has emphasized, a shared numeric scale can still hide genuinely different internal definitions of what each number means.
The second common gap: much of the content in this space cites extremely precise-sounding statistics about inter-rater reliability improvement that don't hold up well to scrutiny — different sources cite meaningfully different "before and after" numbers for what's supposedly the same underlying phenomenon, and at least one detailed "case study" found during research for this piece had no verifiable organization behind it. The genuinely well-established evidence here is that structure and calibration measurably improve consistency and predictive validity (per Schmidt & Hunter and the more recent Sackett et al. re-analysis) — the exact magnitude of improvement is much less reliably documented than confident-sounding secondary sources suggest.
Common Mistakes Companies Make
❌ Assuming a shared scorecard template alone guarantees consistent scoring across interviewers
❌ Including too many competencies per round, causing evaluation fatigue and midpoint-default scoring
❌ Using a numeric scale with no behavioral anchors describing what each rating level actually means
❌ Skipping calibration sessions before interviewers evaluate live candidates for the first time
❌ Weighting every competency equally regardless of its actual importance to the specific role
❌ Treating calibration as a one-time rollout activity rather than an ongoing, recurring practice
Checklist: Is Your Scorecard Actually Standardized?
Every interviewer for a given role uses the same competencies, scale, and behavioral anchors
Ratings require a specific evidence line, not just a number
New interviewers go through a calibration session using a shared example before scoring live candidates
Competency weighting reflects actual role priorities, not automatic equal weighting
Calibration happens on a recurring basis, not only once
You periodically check whether scorecard ratings actually correlate with post-hire performance
Where Tools Fit — and Where They Don't
Given that consistency depends heavily on shared reference points and recurring practice, this is a stage where the right tooling provides genuine, structural support: enforcing the same competencies, scale, and behavioral anchors across every interviewer for a given role automatically, requiring an evidence line before a rating can be submitted, and surfacing calibration exercises and post-hire performance correlation data that would otherwise require manual tracking to uncover. This is exactly the layer FastHire's structured evaluation tools are designed to support — making standardization the default rather than something that depends entirely on individual interviewer discipline.
What no tool can do on its own is write genuinely good behavioral anchors for your specific roles, or run the actual calibration conversation where interviewers compare notes and align their standards. Technology can enforce whichever standard your team has agreed on consistently; the work of actually defining and calibrating that standard still requires deliberate human judgment and practice.
Key Takeaways
A shared scorecard template doesn't automatically produce consistent scoring — standardization requires calibration, not just a shared form.
Schmidt and Hunter's well-established meta-analysis, and the more recent Sackett et al. re-analysis, provide strong, genuine academic backing for structured interviewing generally, even though many specific inter-rater reliability statistics circulating online don't hold up to scrutiny.
Capping competencies at roughly four to six per round, writing specific behavioral anchors, and requiring an evidence line for every rating are the core mechanics that make scoring genuinely comparable across interviewers.
Calibration sessions using a shared example — before live interviews begin — are what actually align interviewers' internal standards, not the scorecard document alone.
Competency weighting should reflect actual role priorities rather than defaulting to equal weighting across every dimension.
Calibration should be an ongoing, recurring practice — particularly as new interviewers join a panel — not a one-time exercise completed at initial rollout.